Lecture 22 Hypothesis Testing
In this lecture we turn from estimation to the second question from lecture 1: are the data compatible with a given claim about ? We first set up the language of hypothesis testing, which lectures 23, 25, 26 and 31 build on, and then construct two tests for the mean of a normal sample.
22.1 Hypotheses
Throughout, follow a parametric model in the sense of definition 1.1. Questions such as whether a coin is fair or whether a treatment has an effect ask whether the true value of belongs to a subset of the parameter space .
A hypothesis is a statement of the form for a subset . In a testing problem, the null hypothesis and the alternative hypothesis are given, where and are disjoint subsets of . A hypothesis is called simple, if the corresponding subset consists of a single point, and composite otherwise.
From now on we write for the value of named by a null hypothesis. In lectures 16 and 17 the same symbol denoted the true value of the parameter; the context makes clear which meaning is intended.
Often we have , and then exactly one of the two hypotheses is true. For example, for the mean of a normal sample, the hypothesis is simple, whereas the one-sided alternative , the two-sided alternative and the one-sided null hypothesis are all composite.
The two hypotheses have different roles: the null hypothesis is the default position, and the alternative is the claim which requires evidence before we can act on it. Section 22.3 makes this distinction precise.
22.2 Tests, Critical Regions and Errors
A test decides between the two hypotheses, and can be described by the set of data values where it rejects .
A test of against is a rule which for every possible data vector decides whether to “reject ” or “do not reject ”. The set
is called the critical region (or rejection region) of the test. Alternatively, a test can be described by its test function for and otherwise.
In practice, the critical region usually has the form or for a statistic given by definition 1.3, called the test statistic, and a constant called the critical value. The two forms give tests with different error probabilities only if has positive probability, as can happen for discrete distributions (exercise 22.3).
A test can decide wrongly in two different ways.
A type I error occurs, if the test wrongly rejects when is true. A type II error occurs, if the test wrongly does not reject when is true.
Table 22.1 summarises the four possible outcomes.
| do not reject | reject | |
| true | correct decision | type I error |
| true | type II error | correct decision |
As an example, in a criminal trial the null hypothesis is the innocence of the defendant, and the alternative is guilt. Convicting an innocent person is a type I error, and acquitting a guilty person is a type II error. Under the standard of proof “beyond reasonable doubt”, many acquittals of the guilty are accepted to avoid wrongful convictions, because a type I error is more serious. Since an acquittal does not prove innocence, the table says “do not reject ” instead of “accept ”.
22.3 The Power Function, Size and Level
Both error probabilities depend on the true parameter value, and can be read off a single function of .
The power function of a test with critical region is given by
i.e. the probability of rejecting when the true parameter value is . For the value is called the power of the test at the alternative .
For the value is the probability of a type I error, and for the value is the probability of a type II error (some books write for the latter). Enlarging the critical region can only increase , which reduces type II errors at the cost of type I errors, and thus we have to choose which probability to control. Since a type I error abandons the default position without good reason, we restrict its probability first and only then consider the power of the test.
The size of a test with power function is given by
For , the test is a level test, if the size of the test is less than or equal to .
For a simple null hypothesis , the size of the test equals . The number is called the significance level and the values and are only conventions. Among all level tests, we prefer the test with the largest power at the alternatives. Lecture 23 shows how to find the most powerful test when both hypotheses are simple.
22.4 Testing the Mean of a Normal Sample
We now construct tests for i.i.d. with known variance . We write for the standard normal distribution function and for the -quantile of the standard normal distribution, i.e. we have . The most commonly used quantiles are and .
We want to test against at significance level . Since a value of much larger than is evidence against , we use as the test statistic and reject if . By proposition A.4, under the standardised mean is standard normally distributed, and thus the probability of a type I error is
Setting this probability equal to , we find the critical value as and thus the resulting test rejects if
This is the one-sided -test. To determine its power, we let . Since is standard normally distributed under , and since by the symmetry of the normal distribution, the power function is
The left-hand panel of figure 22.1 shows this function. As increases the curve gets steeper, and exercise 22.1 uses this to determine the required sample size.
For , , and the test rejects if . At the alternative we have and the power is , at it is only : a shift of a quarter of a standard deviation is detected in barely a third of all samples.
The values belong to neither hypothesis of this example. Since the power function (22.1) is increasing, the test also has size for the composite null hypothesis , which covers these values. This is why definition 22.5 takes a supremum.
To detect departures in both directions, we test against and we reject for . Since is standard normally distributed under and the normal distribution is symmetric, we have
Setting this equal to , we find and thus the two-sided -test rejects if
With as in example 22.6, the same standardisation gives the power function
shown in the right-hand panel of figure 22.1. This function is symmetric about and has its minimum value at this point (exercise 22.2). For , , and the test rejects if and at we have and the power .
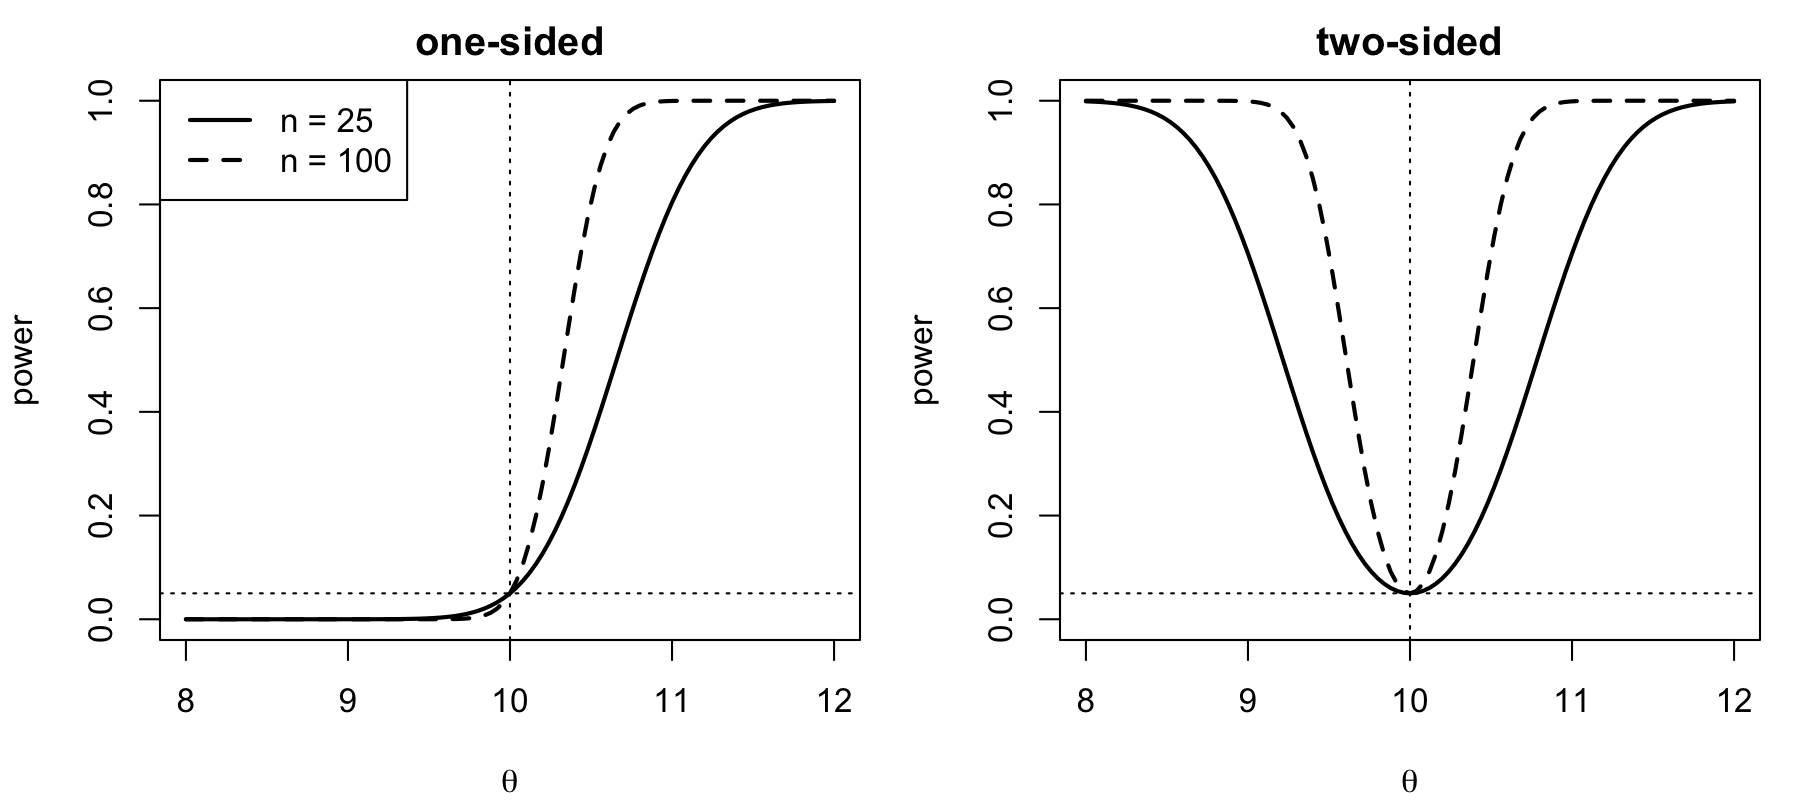
At the one-sided test has power against , since it places all of its type I error probability in the upper tail, but it is useless for alternatives below . Lecture 23 shows that the one-sided test is most powerful against every alternative above , and that no single test is best for both directions. Thus, before we consider the data, we must decide which departures from are of interest.
22.5 The -Value
A test at a fixed level only states whether is rejected. The -value also records how extreme the observed value of the test statistic is under .
For a test which rejects for large values of a test statistic , the -value of the data is given by
For a test which rejects for small values of the inequality is reversed, and the two-sided -test uses .
For a simple null hypothesis the supremum reduces to . Since is the size of the test with critical region , it is the smallest level at which a test of the form rejects , and thus is rejected at level if and only if . In this case we call the data significant at level . For the one-sided -test we find , where is the observed value of , and for the two-sided test we find . In the situation of example 22.6, the observed mean gives and thus for the one-sided test and for the two-sided test.
For a simple null hypothesis and a continuous test statistic, the distribution of the -value under does not depend on the model.
Let be simple and let have a continuous distribution function under . Then the -value of a test which rejects for large values of satisfies for all , i.e. it is uniformly distributed on under .
Fix . Since is continuous, we have . Let be the smallest number with , which exists since is continuous with limits and . Since is non-decreasing, holds if and only if , and thus . This completes the proof. ∎
For a discrete test statistic, e.g. the number of successes in a Bernoulli sample, the -value takes only countably many values and is not uniformly distributed. For an integer-valued , the test which rejects if is the test with the smallest integer of level , and thus it still has size at most . A test whose size is smaller than its level in this way is called conservative.
Since the -value is a probability, it is tempting to misread it. It is not the probability that is true: the parameter is a fixed, unknown number, and the probability in (22.2) refers to the data. Nor does a large -value establish , since data compatible with may be compatible with many alternatives as well: the test from example 22.6 has power only at .
-
•
A testing problem contrasts a null hypothesis against an alternative . A hypothesis is simple, if the corresponding subset of is a single point, and composite otherwise.
-
•
A test is given by its critical region , typically of the form for a test statistic and critical value .
-
•
Type I errors are cases where is true but is wrongly rejected by the test, type II errors are cases where is true but is not rejected. The power function gives the probability of type I errors for and the power of the test for .
-
•
The size of a test is . A level test has size at most . The level is chosen first, and then the power of the test can be considered.
-
•
For the mean of a normal sample with known variance, the one-sided -test has an S-shaped power function and the two-sided -test a U-shaped one. Before looking at the data, we decide which departures from are of interest.
-
•
The -value is the probability under of a test statistic at least as extreme as the observed one, and is rejected at level if and only if . It is not the probability that is true, and a large -value does not establish . For a simple null hypothesis and a continuous test statistic, the -value is uniformly distributed on under .
Consider the one-sided -test from example 22.6, at level , and let be the alternative and be the target power.
-
1.
Show that the test has power at least at if and only if
-
2.
For , , and target power (so that ), determine the smallest sample size which achieves the target power.
-
3.
How does the required sample size change, when the difference is halved? What happens when is doubled?
Consider the two-sided -test from example 22.7, with power function where , and .
-
1.
Show that for all , and conclude that is symmetric about .
-
2.
Show that is strictly increasing on . Conclude that has its minimum value at .
Let be i.i.d. Bernoulli with success probability and consider testing against using the test which rejects if for an integer .
-
1.
Write down the size of the test as a function of , using the binomial distribution of under .
-
2.
Determine the smallest such that the test has level . Compute the size of the test for this case. Justify your answer by showing that no choice of can lead to a size of exactly .
-
3.
Determine the power of the test from the previous part when , and . Comment on the capabilities and limitations of the test with ten observations.
-
4.
Nine successes are observed. Compute the -value and state the decision at level .
Let be i.i.d. as in example 1.2 and let , where the density was found in example 8.9. We test against .
-
1.
Show that for .
-
2.
Consider the test which rejects if , for a constant . Determine the size of this test and the value of which makes the size equal to .
-
3.
Determine the power function of the test from the previous part, and evaluate this function at , , and .
-
4.
Consider the second test, which rejects if . Show that this test has size . Determine the power function of this test and compare the power functions of the two tests. Which of the two tests would you choose and why?
A sample of size from with known has mean . We want to test .
-
1.
Determine the -value of the one-sided -test with against and state the decisions for and .
-
2.
Determine the -value of the two-sided test against and state the same two decisions.
-
3.
Your colleague summarises the first part of the question as “there is a chance that the mean is ”. What is wrong with this sentence? Write one correct sentence to summarise the first part of the question.
-
4.
Verify lemma 22.9 directly for the one-sided -test: show that under the -value with satisfies for all .